
GPT overestimates extreme response options like ‘always’ or ‘never,’ while Opus underestimates them
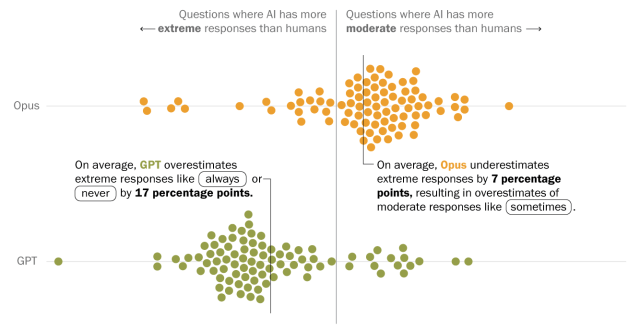
Note: Average percentage point error is calculated only for questions with ordered response categories (89 out of 119 questions tested). Extreme responses include options at the far ends of scales (such as “extremely” or “not at all”). Moderate responses include middle options (such as “somewhat,” “about right” or “neither”).
Source: Survey of U.S. adults and “digital twins” synthetic analysis using models set to low reasoning with extended profile information and expert reflection. Survey was conducted Jan. 20-26, 2026 (replicated March 2-3 with OpenAI GPT-5.1; and replicated March 9-12 and April 7-10 with Claude Opus 4.6).
“Can AI Stand In for Human Survey-Takers? Not Really”
“Can AI Stand In for Human Survey-Takers? Not Really”
PEW RESEARCH CENTER
